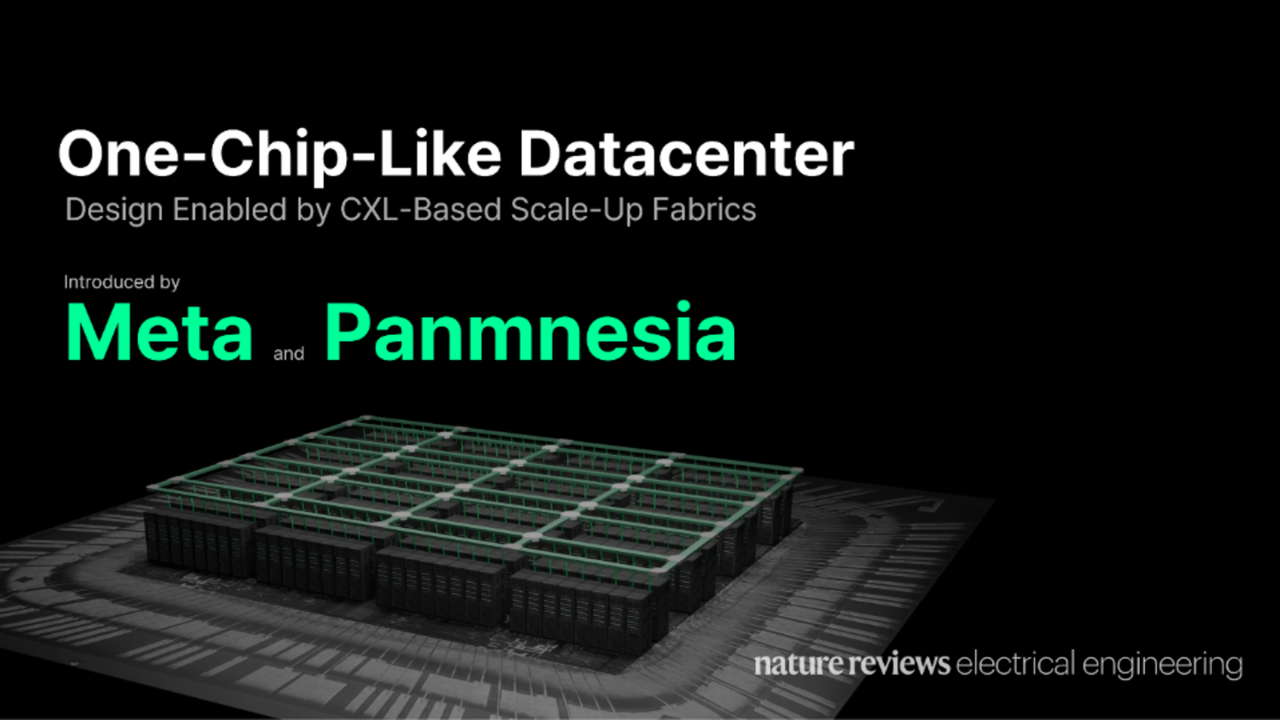
Modern AI clusters have a dirty secret: the GPUs are fast, but the moment a job spills beyond a single rack, it hits a network, and a network means waiting. Meta and Panmnesia, a fabless semiconductor company from Daejeon, South Korea, think the fix is to stop treating a datacenter as a pile of servers and start treating it like one very large microprocessor. Their proposal, built on Compute Express Link (CXL), appears as an invited Review Article in Nature Reviews Electrical Engineering, a Nature Portfolio journal, published in August 2026. Panmnesia announced the work on September 8, 2026.
The idea is what the authors call a tightly coupled system with a single coherence domain: CPUs, AI accelerators and memory spread across multiple racks, yet coordinated as one unit instead of loosely exchanging requests over a conventional network.
According to the companies, the architecture delivers the following against its reference platform:
- Accelerators per CPU: from 2 to 16, an eightfold increase
- Coherence domain: up to 960 accelerators, roughly 13 times the reference platform
- Latency: cross-server access drops from the microsecond range to several hundred nanoseconds, up to an order of magnitude lower
- Failure handling: the unit of replacement shrinks from a whole server to a single device
Blocks & Files reports that the comparison baseline is Nvidia’s GB200 NVL72, the rack-scale system that defines the current state of the art for tightly coupled AI hardware.
Three pieces of silicon make it work. A high-fan-out non-blocking switch cuts the number of hops while keeping path lengths consistent, so accesses that used to leave the rack follow a fixed, predictable route. A link acceleration unit (LAU) dedicates hardware pipelines to protocol processing, smoothing out behaviour at each hop. And a fabric controller enforces the same request-handling policies across the whole system. Because electrical signals only travel so far, the design also leans on CXL-over-optics to extend the fabric over longer datacenter distances without abandoning the CXL model.
“As AI systems continue to scale, the ability to connect large numbers of accelerators and memory devices quickly and efficiently is becoming just as important as the performance of individual accelerators,” said Myoungsoo Jung, CEO of Panmnesia.
This is not purely a paper exercise. Panmnesia says its CXL/PCIe fabric controller and link acceleration unit have completed silicon validation, while the fabric switch has been fabricated, with pre-release silicon undergoing testing. The company says it is preparing the core components for commercial supply. Still, what was published is an architectural proposal backed by selected chips, not a working 960-accelerator deployment.
The pitch lands at a moment when interconnects increasingly decide how far AI training can scale. Proprietary links keep things tight inside a rack; Meta and Panmnesia are betting that an open standard, carried over optics, can keep that same tightness across many of them.